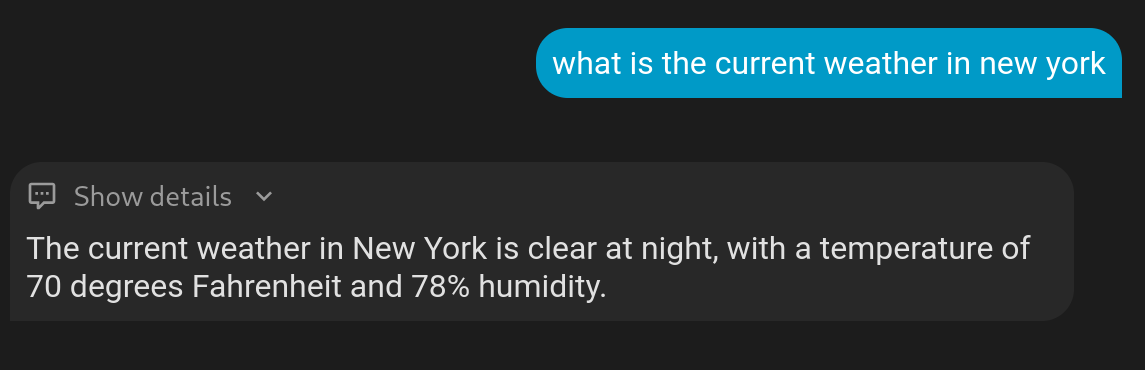
@autumn this setup is super fucked and slow speech recognition running on a raspberry pi gemma E4B running on a desktop gpu charlie kirk tts running on my laptop home assistant won't stream it in real time for some reason
@karebu honestly the way ive got it setup, whisper/piper on my main server (on CPU) and ollama on my desktop for the model, its like almost instant for everything. i wanna try do the voice thing so fucking bad tho 😭😭😭 what's that ui you're using btw?
i switched just now from whisper to qwen3-asr running on llama.cpp on the same system running gemma and now it's instantaneous. still haven't figured out the tts issue though.
@karebu also i get like 180 t/s on it or something extremely stupid so im not fussed lmao, if you havent already then start using the gemma QAT models on hf they're great